Generated results
All rates describe synthetic test opportunities, NOT historical flight risk. Seeds, settings, complete Boolean suites and analytic comparisons are in study.json.
| Experiment | Trials | Latent triggers | Navigation losses | Detected | Rate | Wilson 95% interval |
|---|---|---|---|---|---|---|
| million_legacy | 1,000,000 | 0 | 0 | 0 | 0.000000% | [0.000000%, 0.000384%] |
| expanded_faithful | 100,000 | 25,005 | 25,005 | 25,005 | 25.005000% | [24.737567%, 25.274354%] |
| rare_tail_faithful | 200,000 | 96 | 96 | 96 | 0.048000% | [0.039312%, 0.058607%] |
| expanded_idealized_stub | 100,000 | 25,005 | 0 | 0 | 0.000000% | [0.000000%, 0.003841%] |
| expanded_packet_oracle | 100,000 | 25,005 | 25,005 | 0 | 0.000000% | [0.000000%, 0.003841%] |
| expanded_alignment_removed | 100,000 | 25,005 | 0 | 0 | 0.000000% | [0.000000%, 0.003841%] |
Conditional detection budgets
| Assumed per-test detection p | Tests for at least 95% detection probability |
|---|---|
| 0 | No finite budget |
| 1e-06 | 2995731 |
| 0.0005 | 5990 |
| 0.01 | 299 |
| 0.25 | 11 |
Multivariate coverage
| Suite | Cases | Pair coverage | Navigation losses | Detected |
|---|---|---|---|---|
| exhaustive | 256 | 100% | 4 | 2 |
| greedy_pairwise | 8 | 100% | 0 | 0 |
| pairwise_blind_witness | 8 | 100% | 0 | 0 |
The blind witness is deliberately constructed from non-failing candidates. It proves that 100% pairwise coverage does not imply detection; it does not estimate typical pairwise effectiveness.
Barrier ablations
| Change | Failed units | Navigation available | Unsafe command | Safety oracle detects |
|---|---|---|---|---|
| baseline_identical_pair | 2 | False | True | True |
| one_unit | 1 | False | True | True |
| three_identical_units | 3 | False | True | True |
| remove_postlaunch_alignment | 0 | True | False | False |
| guard_alignment_conversion | 0 | True | False | False |
| isolate_alignment_exception | 0 | True | False | False |
| reject_diagnostic_frame | 2 | False | False | True |
| idealized_sri_stub | 0 | True | False | False |
Detection prerequisites: controlled removals
One known injected case is distinct from a random campaign. The design stays vulnerable except for the guarded negative control. The existing matched Monte Carlo runs establish support/harness/oracle contrasts; this experiment adds deterministic process controls, not random draws.
| Control | Actual navigation loss | Injected case detected | Random budget | P(at least one detection) | 95% target met | Replay retained | Modeled response blocks |
|---|---|---|---|---|---|---|---|
| All prerequisites present | True | True | 5,990 | 95.000084% | True | True | True |
| No overflow exposure | False | False | 5,990 | 0.000000% | False | False | False |
| Wrong lifecycle only | False | False | 5,990 | 0.000000% | False | False | False |
| Idealized SRI stub | True | False | 5,990 | 0.000000% | False | False | False |
| Packet-only oracle | True | False | 5,990 | 0.000000% | False | False | False |
| Too little random budget | True | True | 10 | 0.498876% | False | True | True |
| No replay evidence | True | True | 5,990 | 95.000084% | True | False | False |
| No enforced response | True | True | 5,990 | 95.000084% | True | True | False |
| Guarded negative control | False | False | 5,990 | 0.000000% | False | False | False |
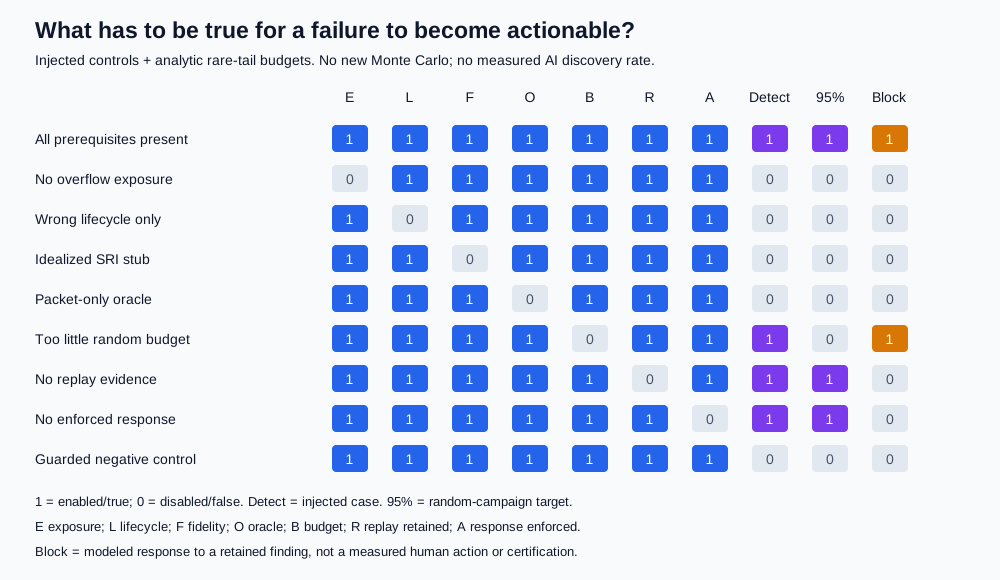
The complete seven-switch grid has 128 distinct configurations: 32 actual navigation losses, 8 injected detections, 4 replayable findings, and 2 modeled response blocks. 4 configurations meet the conditional 95% discovery target; 1 also retains evidence and enforces the modeled response. These counts enumerate a designed truth table, not an empirical readiness score, probability of human response, or AI discovery rate. With the specified rare-tail detection p=0.0005, the minimal 95% budget is 5,990. A smaller budget can still detect a fault; it does not meet that target. Replay retention and response policy are downstream of detection. The executable core has not changed. The protected negative control prevents this modeled failure even with all test prerequisites enabled. Exact equations, replayable cases, and all rows are in study.json; see methods and the future-testing guide.
Interpretation
The expanded, idealized and packet-oracle runs use identical inputs and seeds. A stub removes the modeled bug; a weak oracle conceals the failure. For zero detections in 1,000,000 iid trials, the exact one-sided 95% upper bound is 2.99572778635e-06 under that test distribution only. For masked-oracle runs, an interval on detected events is not an interval on actual failures. No flight telemetry, original Ada binary, calibrated BH model, or blinded AI evaluation is present.